Why This Matters More Than Another AI Coding Toy
Every cross-border operator I know is running the same silent experiment right now: how much of the operational grind can we hand to an agent without losing control of the store? We’ve all watched the demo videos — AI that “manages your Amazon listings” or “handles your customer service” — and then we’ve all watched those same tools fumble a simple price change or send a refund to the wrong order. The gap between the polished pitch and the messy reality of a live Seller Central account is where most AI tooling dies. So when a maker with a track record like Worathiti Pung — the person behind Superagent — ships something that claims to give Claude Code an actual computer to operate, I pay attention. Not because I need another coding assistant, but because the underlying architecture — a visible browser, a phone in the loop, per-task isolation — is exactly the control layer that’s been missing from every “autonomous agent” pitched at e-commerce sellers. This isn’t a review of a developer tool. It’s a look at what happens when an agent finally has to sit in the same chair you sit in.
The Real Problem: Agents That Work Blind
Let me paint the picture that every Amazon FBA operator recognizes. You’ve got a tool that’s supposed to reconcile your inventory across three warehouses, update your Shopify product descriptions, and respond to a TikTok Shop customer dispute. The tool runs. It tells you it’s done. You tab over to check — and nothing changed. Or worse, something changed that you didn’t ask for. The agent worked in a headless environment, a phantom browser that never actually rendered your dashboard, never saw the CAPTCHA, never noticed that the variant selector was in a different position today. It reported success because the API call returned a 200, not because the human-visible outcome was correct.
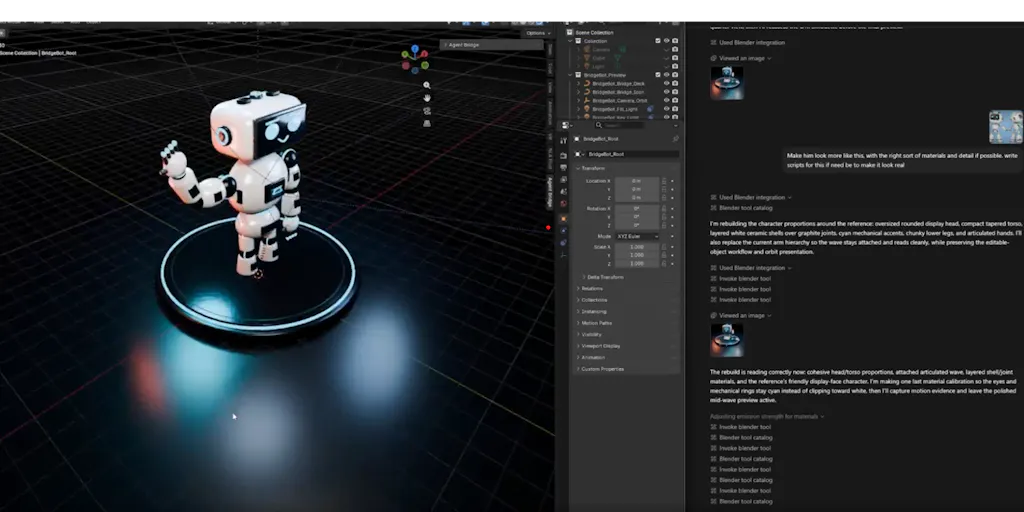
CakewordAI — the product name on this launch — attacks that problem from a different angle. Instead of pretending the agent can operate in the abstract, it gives the agent a real browser, running on your screen, logged into your actual sessions. You watch it work. You can grab the mouse back mid-click. That’s not a luxury feature; that’s the difference between an agent that’s genuinely useful for a production environment and one that’s only good for demos.
The maker’s own framing is telling: Claude Code writes code, then hands you “a wall of scrolling text, forgets everything the moment you close the window, and leaves you alt tabbing to check whether the page actually changed.” Every seller who has tried to automate their repricing or their review management knows exactly that feeling. The agent did something — you’re just not sure what, or where, or whether it’s reversible.
Why Amazon Sellers Should Care More Than Shopify Ones
Here’s the asymmetry. A Shopify store is comparatively forgiving — you can duplicate a theme, roll back a change, and the API surface is clean and well-documented. Amazon Seller Central is a different beast entirely. The interface is older, the API is more restrictive, and the cost of a wrong action — a listing suppressed, a buy box lost, a compliance flag raised — is immediate and financial. An agent that operates blind in that environment is a liability, not an asset. The visible browser approach in CakewordAI matters more for Amazon operators because the stakes are higher and the feedback loops are slower. You don’t find out the agent mis-categorized your product until the listing is already suppressed.
What Actually Makes This Different
Let me be specific about the architecture, because the difference between this and the incumbent tools is structural, not cosmetic.
A real browser, not a headless one. The launch post is emphatic: “The one on your screen, in your own logged in sessions, which you watch and can take back mid click. Not a headless one you never see.” For anyone who has tried to use Helium 10 or similar tools to automate parts of their Amazon workflow, this is the missing piece. Headless browsers break constantly because they don’t render JavaScript the same way, they don’t have the same cookies, they don’t have the same session state. A real browser on your screen is a browser that sees what you see. When the agent navigates to your Seller Central dashboard, it’s seeing the same layout, the same warnings, the same pop-ups that you would see.
An iPhone in the window. The product streams a real iOS Simulator from its framebuffer — the agent can tap and swipe through an app it’s building or testing. For cross-border sellers, this is interesting for a specific reason: mobile-first markets. If you’re selling on TikTok Shop or through a mobile-heavy marketplace in Southeast Asia, the mobile experience is the experience. An agent that can actually interact with the iOS app, not just mock the API, is an agent that can verify the mobile checkout flow actually works before you push it live.
Your phone in the loop. This is the piece that made me stop scrolling. The iOS app pairs via QR code, and you approve actions from your sofa. End-to-end encrypted, through a relay that “holds no key and stores nothing.” The operational implication for a seller is significant — you can kick off a long-running task, walk away, and still have veto power over the critical junctures. You’re not chained to the desk watching the agent work; you’re approving the moments that matter from wherever you are.
A room per task. Each chat runs on its own git worktree, commits on its own branch, and never touches your main checkout. For a seller who’s running a team — even a small one — this is the difference between an agent that’s a collaborator and an agent that’s a liability. Two agents editing the same file an hour apart is the classic failure mode. A worktree per task eliminates that class of problem entirely.
Private by default. No account, no server, no telemetry, no second subscription. It runs Claude Code locally on the plan you already pay for. The Mac app, the iPhone app, and the relay are all MIT licensed on GitHub. For sellers who’ve been burned by tools that hold their data hostage or change their pricing model mid-contract, this is a meaningful trust signal.
Where the Math Breaks
Let me be the skeptic here, because the launch thread’s own commenters raise the point I’d raise. Rabnoor Singh nails it: “watching doesnt scale. i watch the first ten minutes and then i stop, and the thing it does at minute forty is the one that actually mattered.” That’s the fundamental tension with any supervised agent. Your attention is a finite resource, and the whole point of an agent is to free your attention, not to consume it differently.
The commenter’s proposed solution is the right one: an allowlist on actions rather than on sites. Reading anything is fine. Clicking something that “sends, posts, pays or deletes” should come back to you. That’s a short list, and it’s enumerable. The product as launched doesn’t seem to have that granularity built in — it’s a human-in-the-loop model, not a policy-based permission model. For a solo operator, that’s workable. For a team running multiple stores across marketplaces, that’s a bottleneck.
Asad M. pushes the same point further: “An agent can’t tell reading my inbox from sending from it, both are a tool call that returns success, and only one of them spends something I don’t get back.” That’s the real risk boundary for sellers. The agent that can read your supplier’s email can also reply to it. The agent that can view your ad spend can also change it. The tool call returns success either way — the difference is whether you’re out of money.
Where the Math Breaks
The pricing model here is “bring your own Claude Code subscription.” That’s elegant for the user — no second subscription, no per-seat fee on top of what you’re already paying. But it also means the cost structure is tied to Anthropic’s pricing, which is usage-based. A seller running heavy automation across multiple marketplaces could see their Claude Code bill climb quickly. The math works beautifully for a light user; it gets interesting for a power user running agents daily across a full product catalog.
What Cross-Border Sellers Can Borrow From This
Even if you never install this tool, the architecture is a blueprint for how to think about agent automation in your own operation.
Insist on visibility. Any tool you run against your Seller Central, your Shopify admin, or your TikTok Shop dashboard should show you what it’s doing in real time. If a tool can’t show you the browser it’s driving, assume it’s working blind and will eventually do something expensive and wrong.
Demand reversibility. The worktree-per-task model is the gold standard. Every agent action should be isolated, versioned, and reversible. If a tool doesn’t give you a clean rollback path, you’re not automating — you’re gambling.
Build a permission boundary. The commenters on this launch are right — the action-level allowlist is the product boundary that matters. Before you hand any agent access to your marketplace accounts, enumerate the actions that are safe to take autonomously (reading, searching, compiling) and the ones that must always require human approval (sending, paying, deleting, posting). That list is short. Write it down.
Keep the human in the loop, but don’t make them the bottleneck. The phone-in-the-loop model is a good compromise — you’re not watching every step, but you’re approving the ones that matter. The failure mode is when the approval cadence becomes so frequent that you stop paying attention, which is exactly when the agent does something costly.
Where My Judgment Says It Falls Short
I want to be direct about the limitations, because the launch post is heavy on enthusiasm and light on edge cases.
The attention problem is unsolved. The product gives you the ability to take back control mid-click, but it doesn’t solve the problem of knowing when you should. The agent will still do something wrong at minute forty that you don’t catch until minute forty-one. The action allowlist that commenters are asking for isn’t in the product as described. That’s a real gap.
The multi-account reality is unaddressed. Cross-border sellers don’t run one Amazon account or one Shopify store. We run multiple marketplaces, multiple regional stores, multiple brand sites. The product as described is built around a single Mac, a single set of logins, a single browser window. The scenario where an agent needs to operate across three Seller Central accounts and two Shopify stores simultaneously — with different permission levels for each — is not covered.
The compliance question is open. For Amazon specifically, any tool that automates seller actions needs to be evaluated against Amazon’s Terms of Service. Amazon has been aggressive about penalizing sellers who use automation that violates their policies. A tool that drives a real browser on your own logged-in session is arguably more compliant than one that uses a headless browser or API workarounds — but “arguably” is not “definitively.” I’d want to see a clearer statement on this before running it against a production account.
The iOS Simulator is niche for most sellers. The ability to test an app in a simulated iPhone is genuinely useful for DTC brands with their own mobile apps, but for the majority of sellers operating through marketplaces, this feature is irrelevant. It’s a signal of the maker’s background, not a solution to a seller’s problem.
What I’d Watch / Test Next
Here’s what I’d do this week, as a cross-border operator evaluating this category of tool:
Run a read-only pilot. Pick one low-risk task — say, pulling your daily sales report from Seller Central and compiling it into a summary. Run it through a tool like this and watch it work. Don’t give it any write permissions. Verify the output against what you’d produce manually.
Write your action allowlist. Take the commenters’ advice before the product does. Sit down with your team and enumerate the actions an agent is allowed to take autonomously versus the ones that require human approval. This is a valuable exercise regardless of which tool you end up using.
Test the phone-approval flow. The relay-based approval model is worth testing in a real scenario — kick off a task, walk away, and see how it feels to approve or reject an action from your phone. Does it give you confidence, or does it create anxiety? That feeling tells you a lot about whether this workflow fits your operation.
Watch the GitHub repo. The MIT-licensed codebase is a gift. Read the relay implementation, check the telemetry claims, and see how the team handles security issues. A tool this powerful deserves scrutiny before it touches a production account.
The direction here is right. The industry has been moving toward visible, supervised, reversible agent automation — and this launch is a meaningful step in that direction. The gaps — action-level permissions, multi-account support, compliance clarity — are the next battlegrounds. The maker who solves those will own the category. For now, this is worth watching, worth testing read-only, and worth holding to a high standard before it touches your live store.