The orchestration layer is coming for your ops stack — and cross-border sellers should be paying attention
Every cross-border operator I know is quietly running a shadow AI stack. One person has Claude drafting listing copy in a browser tab, another has ChatGPT summarizing supplier emails, a third has some half-broken script pulling Amazon Seller Central reports into a spreadsheet. Nobody has a map of it. Nobody knows which agent touched which SKU. And when something breaks — a listing goes live with the wrong HS code, a supplier quote gets misread — the post-mortem is basically archaeology.
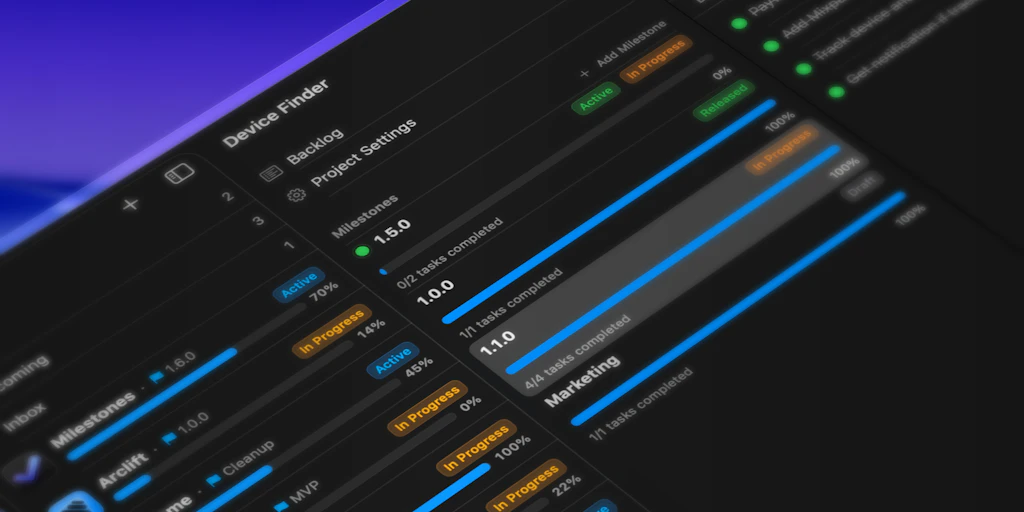
That is exactly the problem ManyAgents is poking at, even though its maker, Stu Green, built it for software engineers. The launch thread is a small window into a much bigger shift: the tooling conversation is moving from “which model is smartest” to “how do I supervise ten of them without losing my mind.” For sellers running lean teams across Shopify, Amazon, TikTok Shop, Temu, and a logistics spreadsheet that nobody wants to own, that shift matters more than any single model release.
What ManyAgents actually solves (and why it’s not really about code)
Strip away the developer framing and the core insight is simple: the bottleneck in agentic work isn’t generation, it’s coordination and review. Green says he built it because he kept losing track of “10+ agents across projects” — writing code, reviewing changes, running tests, coordinating work — and that across several projects the count “can triple.” That’s the same failure mode a seller hits when they’ve got one agent researching keywords, one writing PDP copy, one reconciling FBA reimbursements, one drafting supplier RFQs, and one summarizing ad performance.
His answer is structural. Each project gets an orchestrator that hands work to agents running in their own git worktrees, a reviewer checks the output, and agents can test changes in a built-in browser beside the chat. Every question an agent needs answered “lands in one place.” That last bit is the actual product. Not the orchestration graph, not the worktrees — the inbox.
Why Amazon sellers should care more than Shopify ones
Here’s my read: pure DTC Shopify operators can get away with a single well-prompted assistant because their surface area is small — one storefront, one catalog, one checkout. Amazon FBA brand owners cannot. Their work is inherently multi-threaded and adversarial: listing compliance on one side, ad spend on another, inventory reconciliation on a third, and a marketplace that will happily suppress your buy box while you’re not looking. That’s a coordination problem disguised as a content problem. A tool that forces every agent question into one queue with project context attached is closer to what an Amazon ops lead actually needs than another copy generator.
The commenters in the thread are already pushing on exactly the right details. Neeraj Nathany asks whether each question shows which project it came from. Leo Heo asks whether a question can show which other tasks are waiting on the answer. Oleksii Sekundant wants the project and proposed decision beside each question “so I can answer without reopening every thread.” Those are not developer nitpicks — they’re the requirements for any human-in-the-loop ops system, whether the “workers” are writing TypeScript or drafting A+ content.
How it differs from the incumbents you’d actually compare it to
Let’s be honest about the competitive set, because the Product Hunt framing undersells how crowded this space is getting.
The closest philosophical cousin is the multi-agent framework crowd — think the orchestration patterns popularized around LangChain and CrewAI. Those give you the plumbing to wire agents together, but they assume you’re comfortable in a terminal and you’re building the supervision layer yourself. ManyAgents’ pitch is that the supervision layer is the product: an inbox, a reviewer, a browser pane, a Mac app. That’s a meaningfully different bet — it’s betting that operators want a cockpit, not a toolkit.
The other comparison is the AI browser and computer-use wave — OpenAI’s operator-style agents, Anthropic’s computer use, and the various “agent that clicks for you” startups. Those are powerful and terrifying in equal measure for anyone who’s watched an agent almost buy the wrong thing. ManyAgents’ reviewer-on-a-different-provider design is a direct response to that fear. As Simon Moxon put it in the thread, “A read-only reviewer on a different provider is the part I like most. Having a second agent check the work before I see it is what made me trust the agents across my projects.”
The read-only reviewer is the sleeper feature
I want to dwell on this because I think it’s the most transferable idea in the whole launch. The reviewer runs on a different provider and is read-only. That’s a deliberate architectural choice, not a feature bullet. It means the thing checking the work can’t also do the work, which kills a whole class of “agent grades its own homework” failures. JC asked the sharpest question in the thread: does the reviewer catch mostly style and consistency issues, or real logic problems the worker missed? Green hasn’t answered that in the scrape, and honestly, that answer is the whole ballgame. If the reviewer only catches formatting, it’s a linter. If it catches logic, it’s a second employee.
For a seller, the analog is obvious and valuable: a read-only agent that checks every generated listing against your brand style guide, your category compliance rules, and your pricing floor before anything goes live. It can’t publish. It can only flag. That’s a much safer primitive than “give the agent your Seller Central credentials and hope.”
What cross-border sellers can borrow from this, regardless of whether they buy it
Even if you never install a Mac app built for engineers, the launch is a useful blueprint. Three things I’d steal immediately.
One inbox for every open question. The reason agent experiments die inside e-commerce teams is that the questions pile up in five different chat windows and nobody owns the answers. Green’s “every question lands in one place” is a design principle you can copy today with a shared Notion database or a Slack channel with a strict format: project, question, proposed decision, blocking tasks. The tool is secondary; the discipline is the product.
Isolation before integration. The git worktree detail sounds irrelevant to sellers until you translate it: every agent works on its own copy, and nothing merges until review. In e-commerce terms, that means agents draft into a staging sheet or a draft listing — never directly into the live catalog. The sellers who get burned by AI are almost always the ones who let it write straight to production.
A second, cheaper model as reviewer. You don’t need the same expensive model to check the work that a cheaper one produced. Running a review pass with a different provider is both a quality control and a cost control. This is the kind of unglamorous architecture decision that separates operators who scale AI from operators who babysit it.
Where the math breaks
Here’s my skepticism. Green is explicit that pricing is undecided — it’s “free for 14 days” and he’s actively asking what people would pay, one-time or monthly. That’s a red flag for anyone building a workflow dependency on it. A tool that becomes your ops inbox is a high-switching-cost purchase, and buying into an unpriced product with an unproven roadmap is how you end up migrating your whole agent stack in six months. For a seller, the honest calculation is: what’s the cost of rebuilding this discipline manually versus the risk of the vendor changing terms? For most teams under $5M GMV, manual discipline wins until the pricing is public and stable.
The second gap is platform coverage. This is a Mac app built around git and browsers. It has no native awareness of Amazon Seller Central, Shopify admin, TikTok Shop Seller Center, or any of the marketplace APIs that actually define a seller’s workday. You’d be bolting your e-commerce agents onto a developer tool and hoping the browser pane is enough. Sometimes it will be. Often it won’t, because the real work happens through authenticated APIs and bulk feeds, not clicks.
The third gap is the one nobody in the thread raised: audit trail. If an agent changes a price or a listing, you need to know who, when, and why — not for fun, but because marketplace suspensions and chargebacks demand it. A review inbox is not the same as an immutable log. I’d want to see that before trusting any orchestration layer with revenue-touching tasks.
Where my judgment says it falls short for this audience
I’ll be blunt: ManyAgents is not built for you. It’s built for a developer with ten coding agents and a merge conflict problem. The cross-border seller is a secondary audience at best, and the launch thread reflects that — every commenter is a builder talking about worktrees and providers, not an operator talking about SKUs and chargebacks.
But that’s precisely why it’s worth watching. The orchestration pattern — orchestrator, isolated workers, independent reviewer, single inbox — is going to get ported into e-commerce tooling within a year, probably by someone building on top of Shopify’s admin APIs or Amazon’s Selling Partner API. The sellers who understand the pattern now will be able to evaluate those tools intelligently instead of buying whatever has the best landing page. The ones who don’t will keep running five browser tabs and calling it a stack.
What I’d watch / test next
This week, before you spend a dollar on any orchestration tool, do the manual version. Pick your three highest-volume agent tasks — say, listing copy, supplier email triage, and ad report summaries — and force every output through a single review queue with a fixed format: source project, proposed output, and the specific decision you need to make. Track how many questions pile up in a week and how long they take to clear. That number is your real benchmark, and it’s the number any tool has to beat.
Then watch two things on ManyAgents specifically: whether Green publishes pricing and answers JC’s question about whether the reviewer catches logic or just style, and whether anyone builds a non-developer template on top of it. If the reviewer turns out to be substantive and the pricing lands under what a junior ops hire costs per month, it becomes a legitimate test candidate for a lean FBA team. If it stays a Mac-only developer toy with vague pricing, file it under “pattern to copy, product to skip” and move on. Either way, the coordination problem it names is real, and it’s coming for your ops stack whether you’re ready or not.